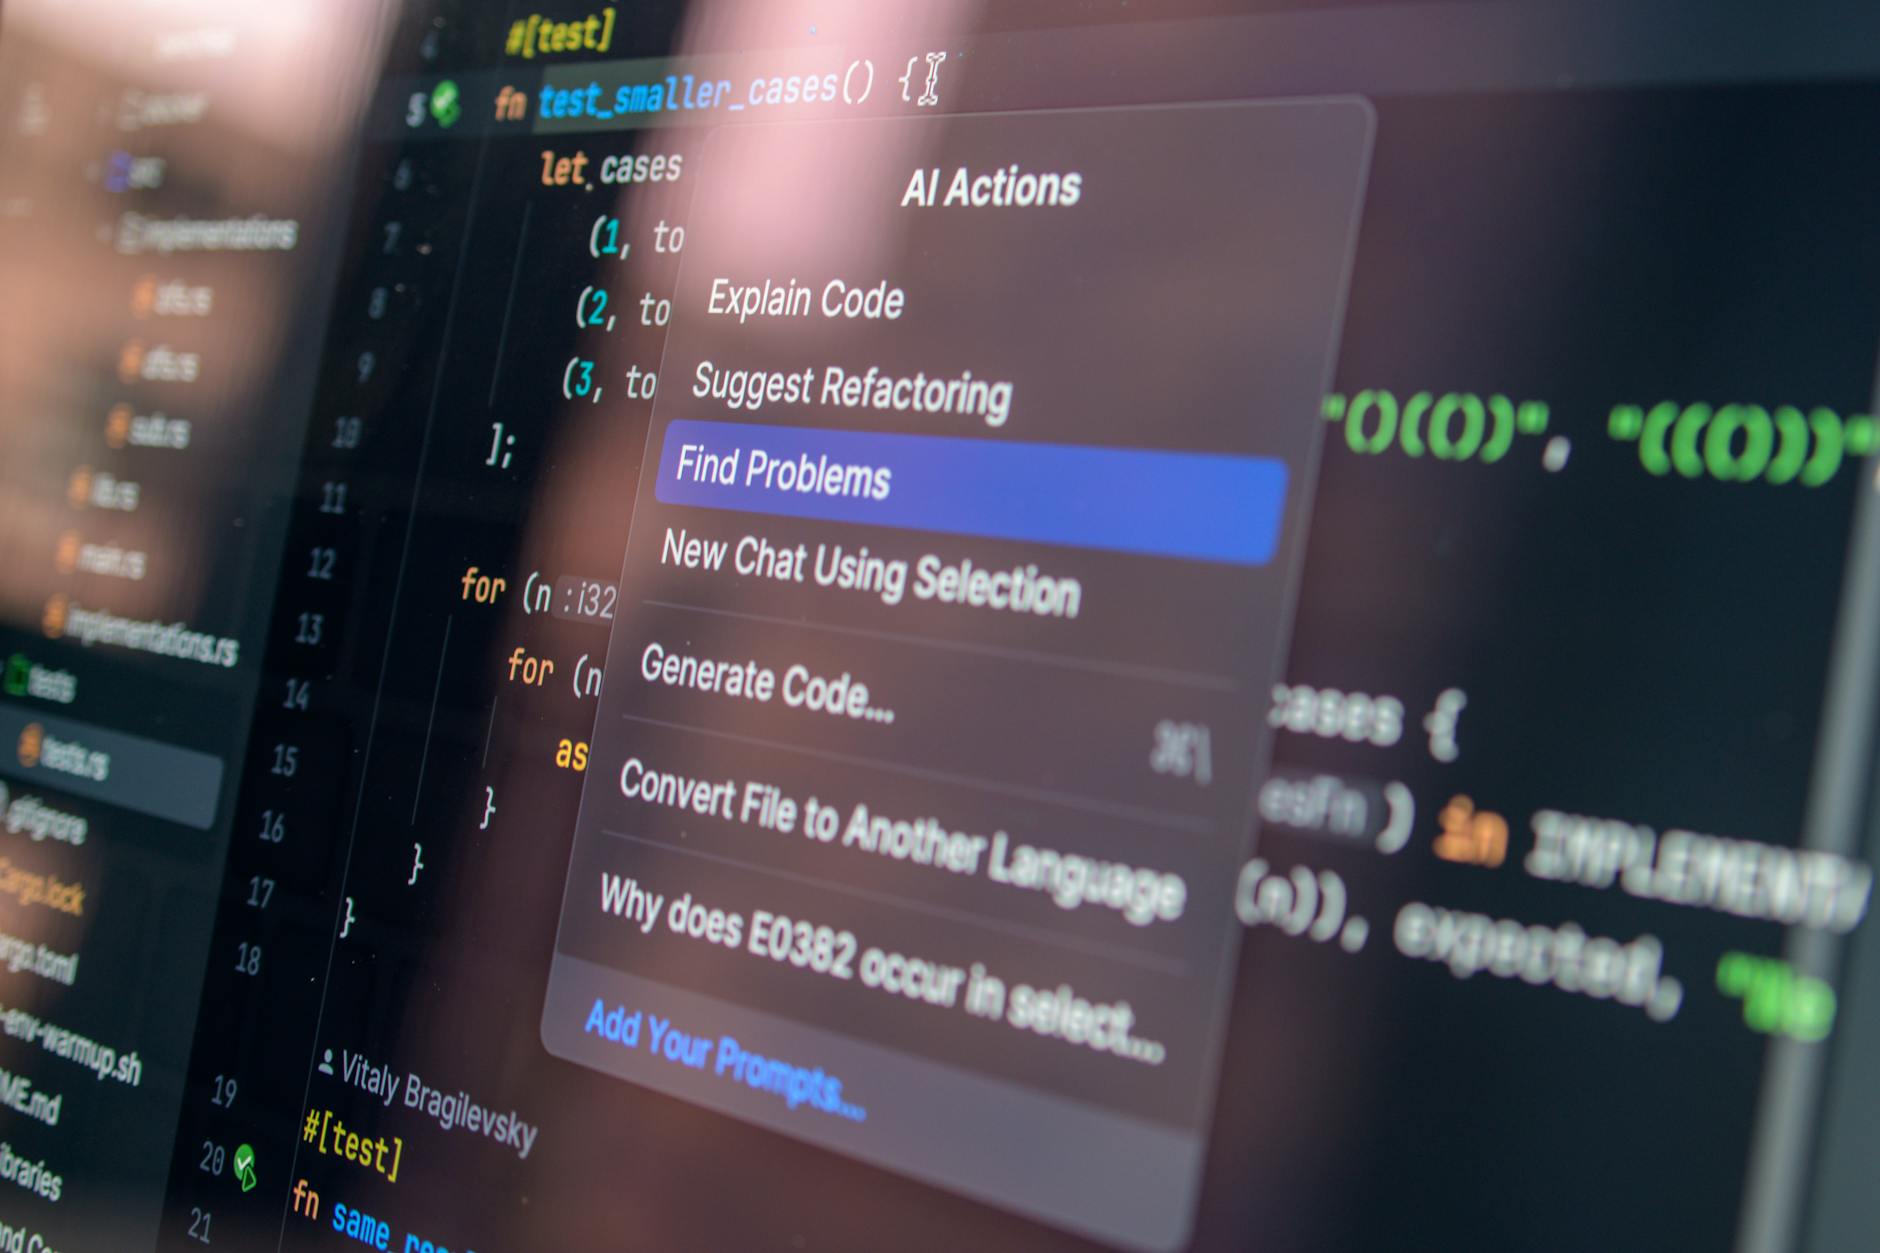
AI Code Review: Where Automated Review Actually Catches Bugs
AI code review tools genuinely catch real bugs before they ship, but they’re reliable for specific categories of problems and weak for others worth knowing in advance.

In this story 6 sections
AI code review tools reliably catch common bug patterns, style violations, and security issues with well-established signatures, but they’re much less reliable at judging whether code actually implements the intended business logic correctly, since that requires context the tool usually doesn’t have available.
A pull request that used to wait hours for a human reviewer can now get automated feedback within minutes, flagging everything from unused variables to potential security holes. That speed is genuinely useful, but it’s worth knowing exactly what these tools are and aren’t actually checking before trusting them with anything important.
This piece covers where AI code review tools reliably add value, where they miss things a human reviewer would catch, and how teams are actually integrating them into a real development workflow today. It’s written for engineering teams deciding how much to trust automated review.
The honest picture is that these tools are genuinely useful as a first pass, catching a specific category of issues efficiently, while still leaving real gaps that require an experienced human reviewer’s judgment to close reliably.
What AI Code Review Catches Reliably
Pattern-based issues are where these tools shine: unused variables, missing null checks, common off-by-one errors, and known insecure coding patterns like unsanitized user input flowing into a database query. These are well-represented in training data and have clear, checkable signatures that don’t require deep contextual understanding of the surrounding system to identify correctly.
Style and consistency issues — inconsistent naming, formatting that doesn’t match the project’s conventions, missing documentation on a public function — also get caught reliably, since these are largely mechanical checks that don’t require deep understanding of what the code is actually trying to accomplish for the business.
Security-focused review has become a particularly strong use case. Known vulnerability classes, like SQL injection risks or hardcoded credentials, get flagged consistently, which is valuable specifically because these issues are cheap to catch early and expensive to catch after deployment, when they might already be live in production and exposed to real users.

What AI Code Review Still Misses
Business logic correctness is the biggest gap. A function can be syntactically clean, well-documented, and free of common bug patterns while still doing the wrong thing entirely, if it doesn’t correctly implement what the product actually needs — and catching that requires understanding intent the tool usually doesn’t have access to at review time, no matter how well-trained the underlying model is.
Cross-file and cross-service reasoning is another weak spot. A change that looks fine in isolation can break an assumption made in a completely different part of the codebase, and unless the review tool has been given that broader context, it has no way to catch the conflict before it ships to production and causes a real incident.
We’ve seen this directly at Emergent Wire in coverage of AI coding agents: the tools that perform best on business-logic-level review are the ones given real access to the surrounding codebase and its tests, not just the isolated diff being reviewed. This connects to the accuracy limitations covered in our piece on whether AI models can do real math, since both problems trace back to the same underlying pattern-matching limitation rather than genuine step-by-step verification.
The Real Cost of False Positives
A review tool that flags too many non-issues creates its own problem: reviewer fatigue, where developers start reflexively dismissing AI feedback because so much of it has historically been noise rather than a genuine issue worth their attention.
This is a real, documented failure mode in tool adoption, not a hypothetical concern — teams that don’t tune their AI review tool’s sensitivity to their own codebase’s actual conventions often end up with a tool generating more noise than signal, undermining the very purpose it was adopted for in the first place. Some teams have gone so far as disabling automated review entirely after a rocky rollout, when a more targeted tuning pass would likely have solved the underlying problem instead.
The teams getting the most value tend to treat initial AI review output as a tunable system, adjusting what gets flagged based on what turns out to be genuinely useful for their specific codebase and team, rather than accepting the tool’s defaults as fixed and unchangeable settings baked into the product.
How Teams Are Actually Integrating AI Review
The common pattern across most serious engineering teams is layered: fast automated checks catch the cheap, mechanical issues early, freeing up human reviewers to focus their limited time and attention on the business logic and architectural judgment calls that automated tools still can’t reliably make.
| Integration Point | What It Catches | Human Role |
|---|---|---|
| Pre-commit hook | Style, obvious pattern issues | Minimal — fast local check |
| Pull request automated comment | Bugs, security patterns, style | Reviews and triages flags |
| Full human review | Business logic, architecture | Primary decision-maker |

The Practical Verdict on AI Code Review
AI code review earns its place as a genuine productivity tool when treated as a fast first pass rather than a replacement for human judgment — it catches real, costly bugs efficiently, and that alone justifies its place in most modern development workflows.
The National Institute of Standards and Technology (NIST) has published secure software development guidance that specifically recommends automated pattern-based scanning as a baseline layer, paired with, not replacing, human review for anything security-critical or business-logic-heavy. Industry analysis from McKinsey has similarly found that engineering teams pairing automated and human review report measurably fewer production incidents than teams relying on either approach alone.
For teams evaluating these tools, the honest question to ask isn’t whether AI review is good enough to replace a human reviewer entirely — it’s whether it’s good enough to make that human reviewer’s limited time meaningfully more effective, which for most teams, it genuinely is. This mirrors the broader tool-use pattern covered in our piece on AI agents that use tools, where the strongest results come from pairing automation with human oversight rather than choosing one over the other.
The Bottom Line
AI code review has earned a real, defensible place in modern development workflows, specifically for the categories of issues it reliably catches: patterns, style, and known security signatures. The gap that remains — business logic correctness and cross-codebase reasoning — is exactly where human review still does the heaviest lifting, and that division of labor looks stable for the foreseeable future.
The teams getting the most value aren’t the ones expecting AI review to replace human judgment, but the ones using it to make human review time count for more.
Emergent Wire covers AI models, capabilities, and the industry building them for readers who want the real story behind the demos.